We keep arriving at the same conclusion from different directions: the best interface for an agent is no interface at all — it's whatever app you already have open. Telegram taught us that. Today's update to the cloud platform takes the idea as far as it goes, and then fixes the two things people actually complained about: the first five minutes, and billing.
The agent is now a coworker in four places
Slack and WhatsApp join Telegram the way you'd expect: connect once in Settings → Connections, then DM your machines like a colleague. Plain text runs a turn on your current session; /machines, /new, /model steer it; the answer lands back in the chat. In Slack the app is a proper AI agent: open its assistant pane and every thread is its own session, with Slack's native "is thinking…" while the agent works. Free on every plan — the channel costs nothing, you pay only for what the agents do. And there's no wrong order: if you have no machine yet, your first message creates one automatically and then runs — and each connection can be pinned to a machine of your choice right on its card.
GitHub is the interesting one. Install the Octomind app on your account or org, and every issue or PR thread becomes a conversation: mention the app in a comment, a 👀 appears while the agent works on your machine, and the answer arrives as a comment in the same thread. Each thread keeps its own session, so parallel PRs stay parallel — and because agent output is already GitHub markdown, replies render like a careful human wrote them.
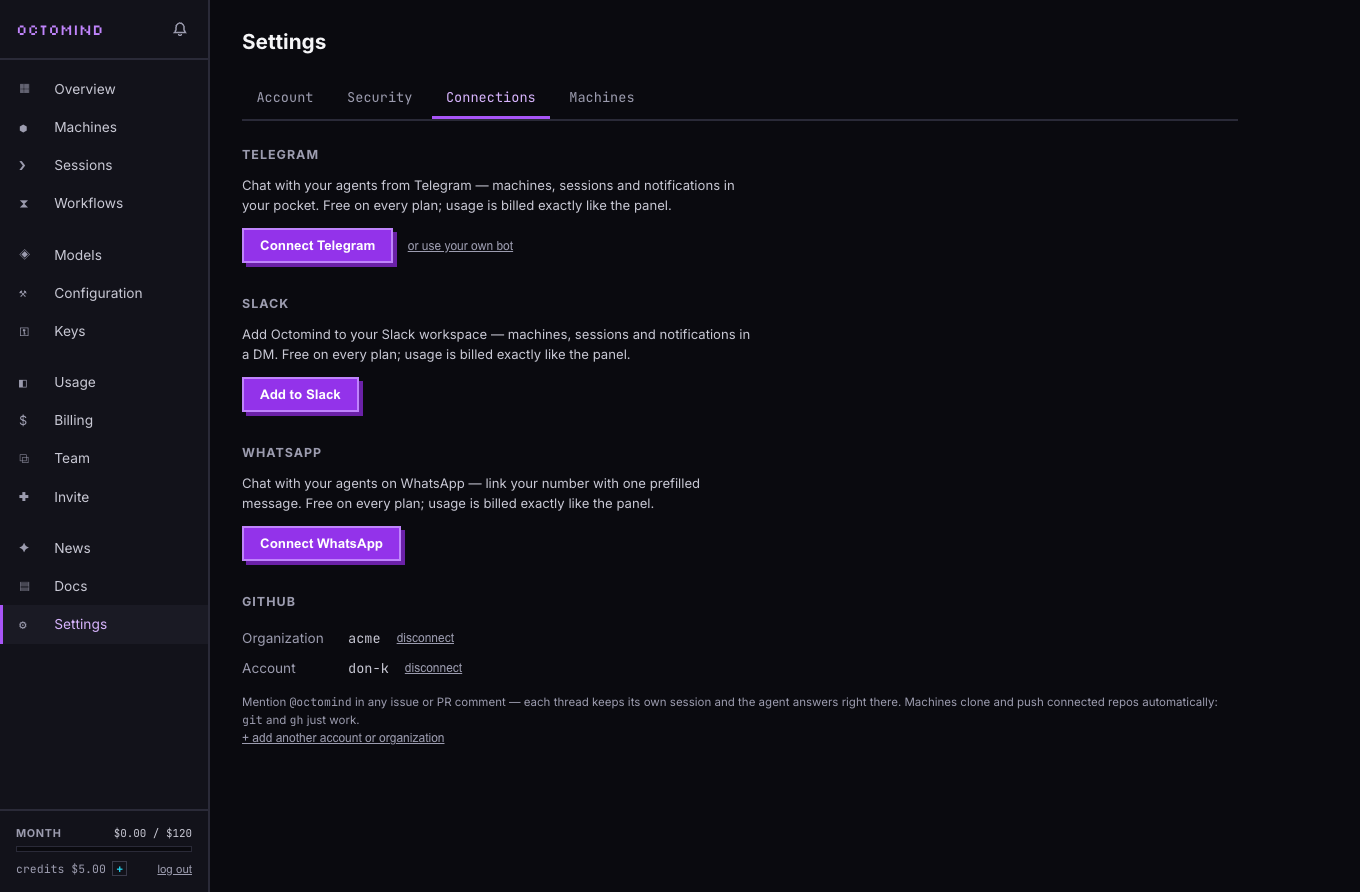
The part I'm proudest of is what you don't see: machines get repo access through tokens scoped to one repo at a time that expire within the hour — git and gh just work, and nothing long-lived ever sits on a machine.
A first five minutes that respects your time
Octomind isn't just for developers, but our first screen used to assume you were one. New accounts now land in a guided start — and the eyebrow says exactly what it costs you: about three minutes.
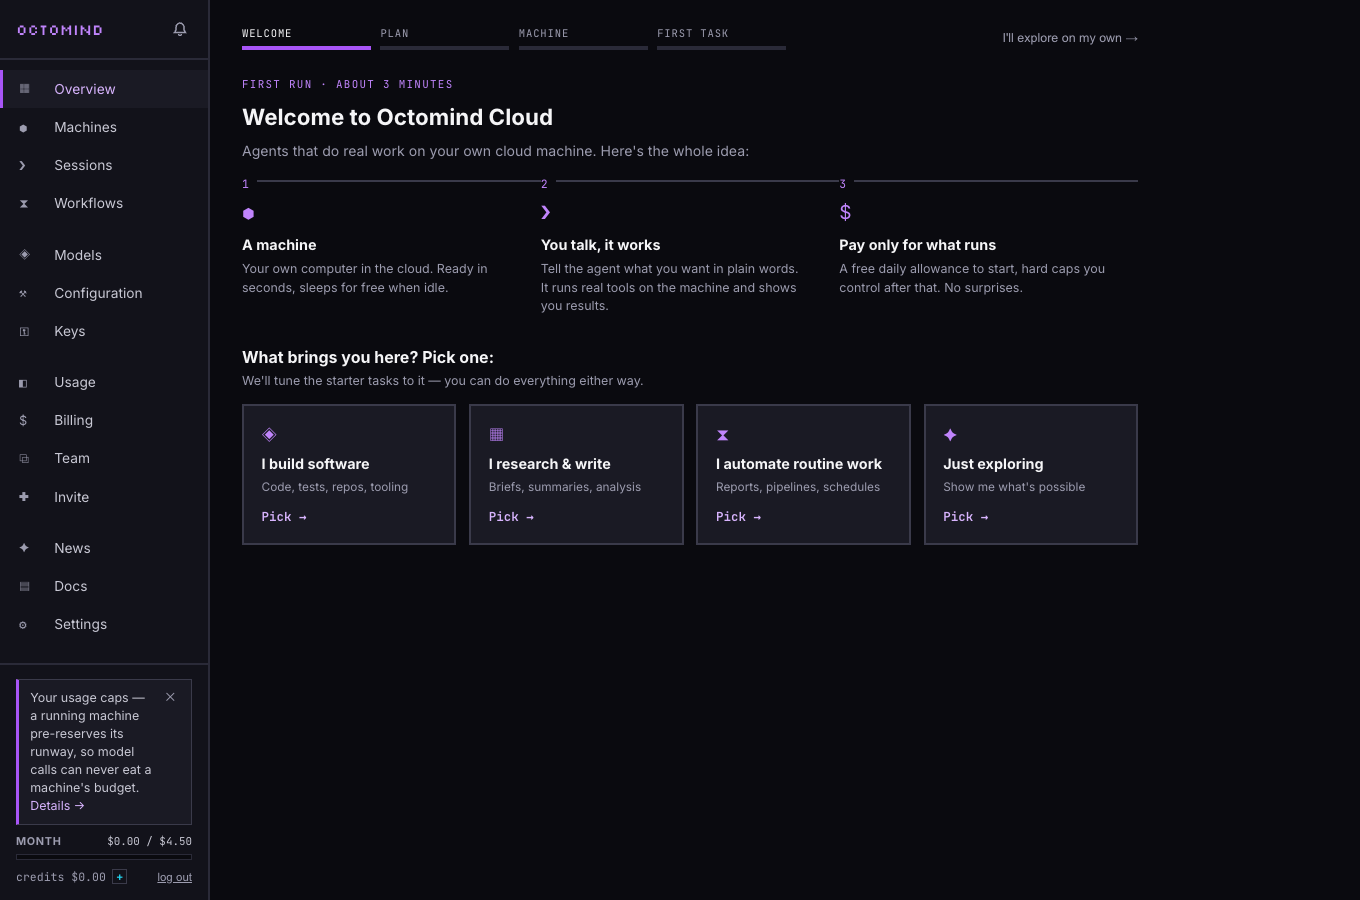
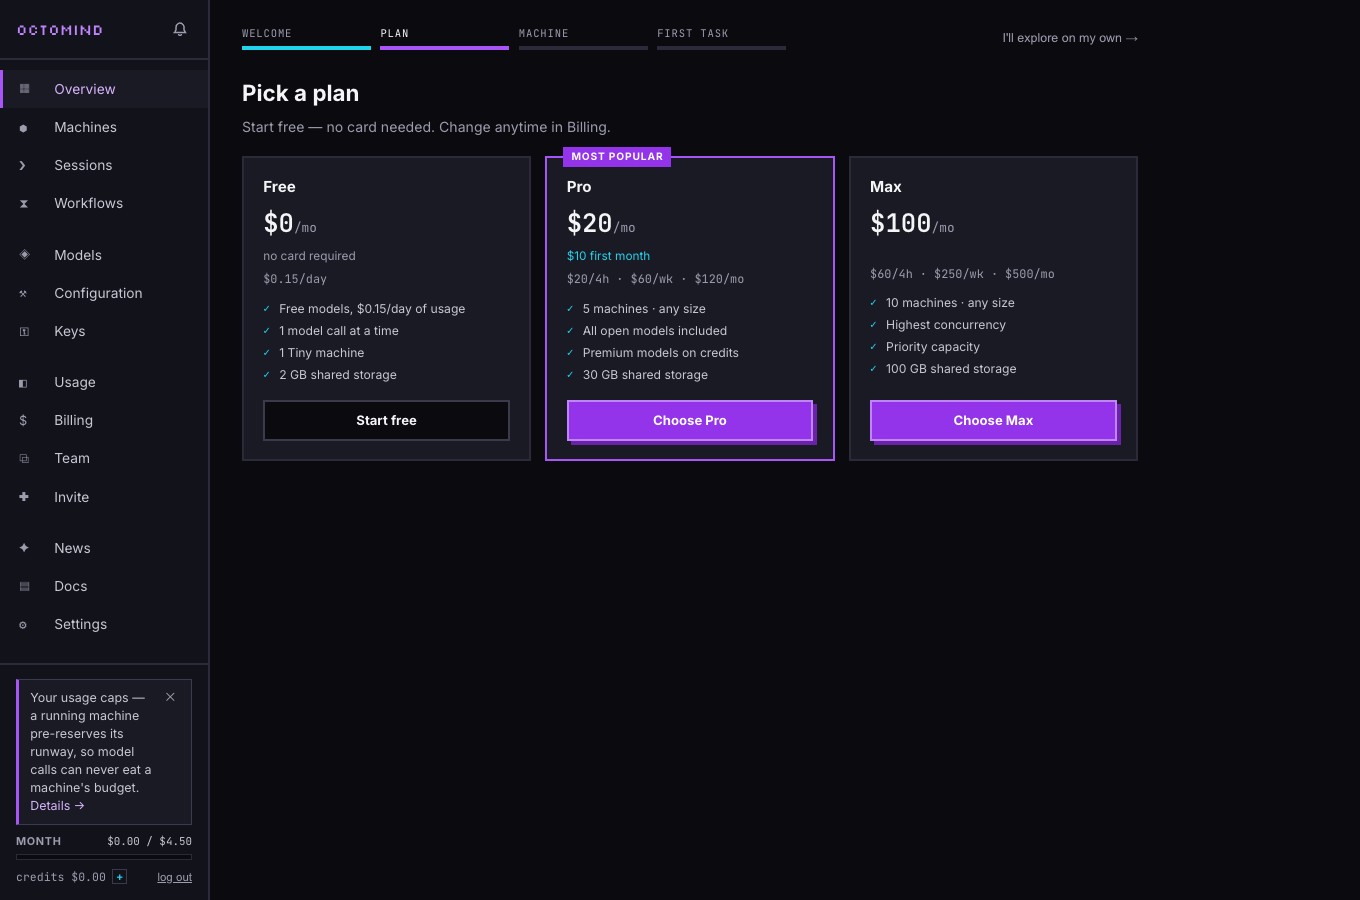
Say what you're here for, pick a plan (Free needs no card), get a machine with one click, and then — the step that matters — hand the agent a real task and watch it work:
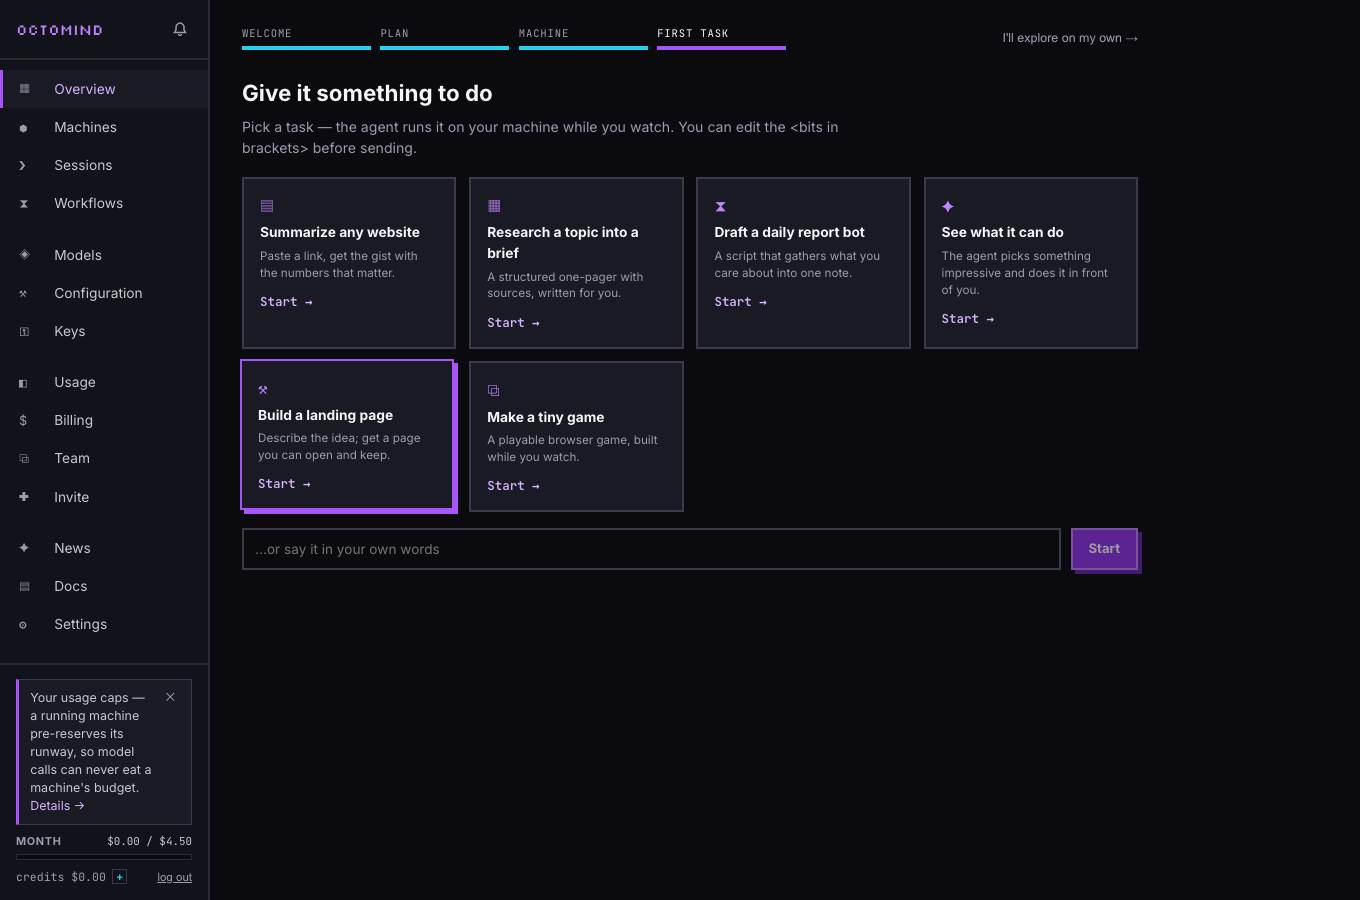
Every step is skippable, and nobody gets herded: skip everything and the setup checklist quietly takes over on the Overview, following your account across devices and retiring itself once you're set up.
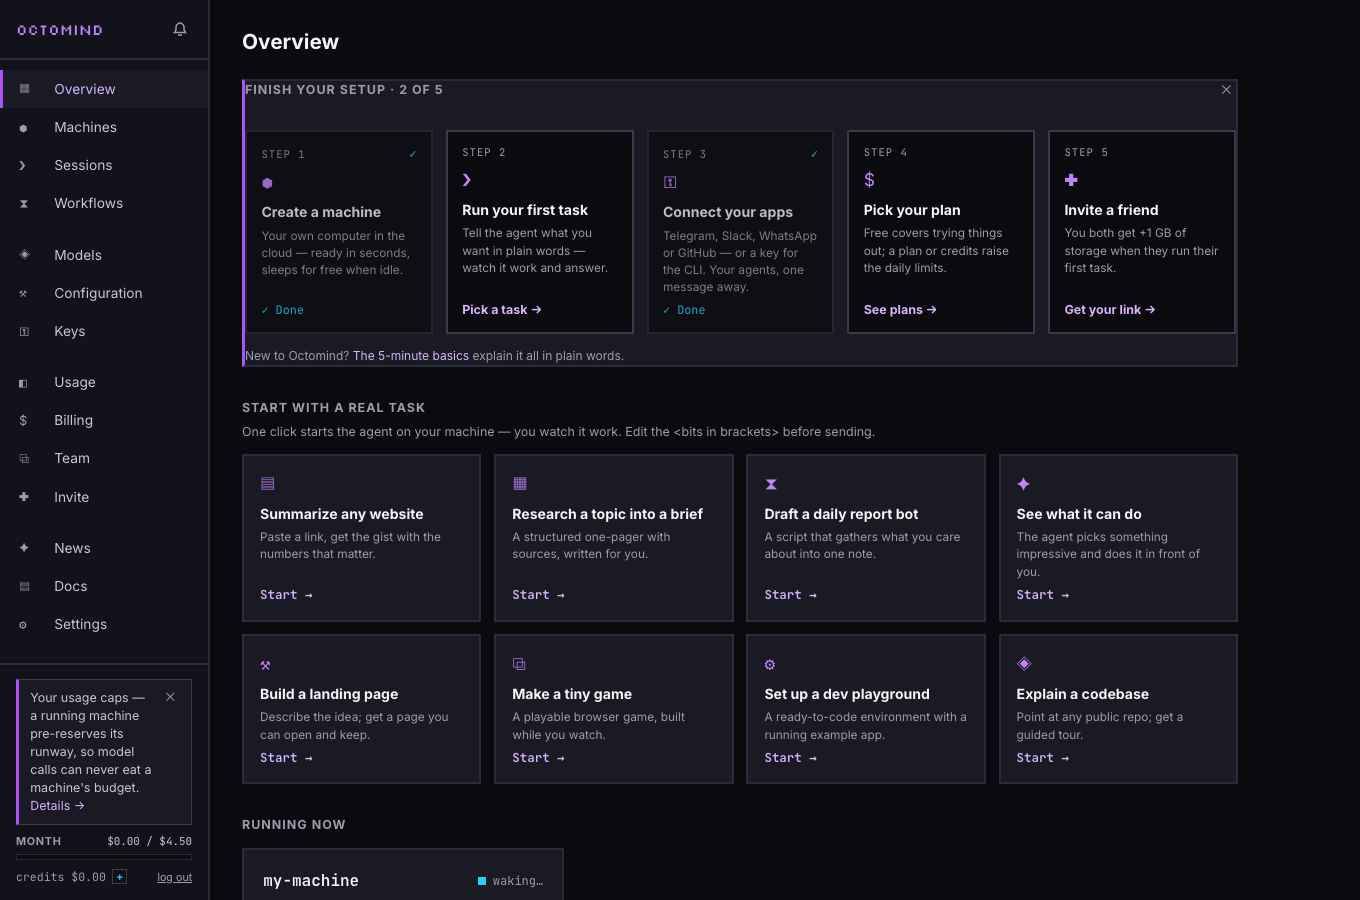
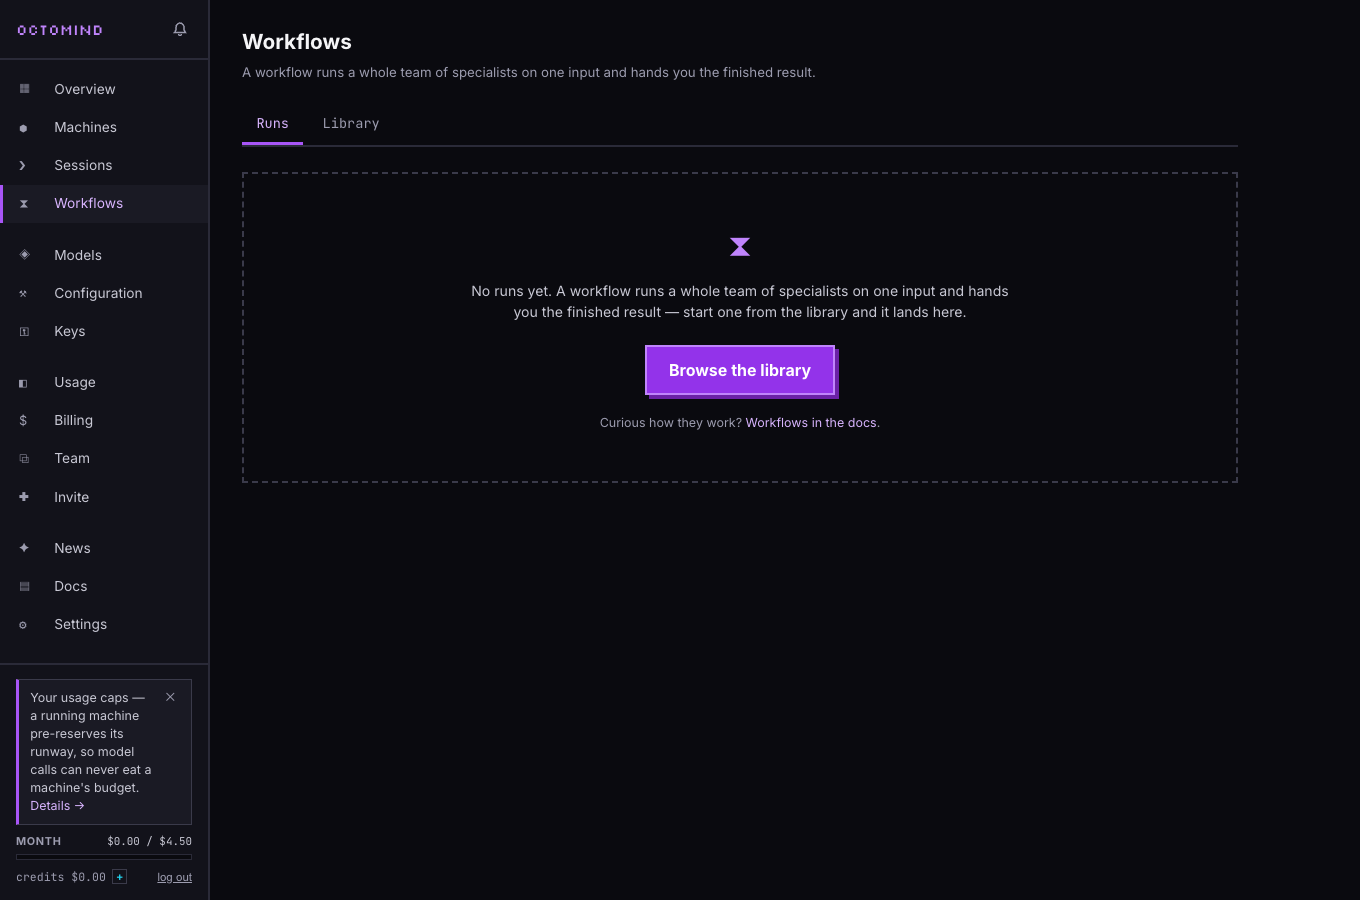
The same philosophy now runs through every empty screen: instead of a blank page, you get one sentence about what the thing is and the one button that starts it. And that button never sends you somewhere else first — starting a session with no machine creates one automatically, in the panel and in every chat connector alike.
Billing that behaves like you'd expect
Two long-overdue fixes shipped together.
Switching plans is instant now. Click Switch to Max and you land directly on Stripe's confirmation showing the exact prorated amount — one click, the higher caps apply immediately. No canceling, no re-subscribing, no support ticket. (Plan choice also shows up right in the first-run flow, where it belongs.)
And caps now reset on your schedule, not the calendar's. Your monthly cap follows your own billing period; weekly caps count in 7-day stretches from it. Subscribe on the 28th or the 1st — a month of caps is exactly the month you paid for. Free plans count from the day you signed up. It sounds small; it's the difference between limits that feel arbitrary and limits that feel like yours.
Also in this update
Inkling Small joined the catalog ($0.50/$1.20 per million tokens, 1M context, included in every paid plan), and so did Qwen3.7 Flash — $0.03/$0.13 per million with a 1M context, in every paid plan. On the credits side: Gemini 3.6 Flash, Gemini 3.5 Flash Lite, and Qwen3.8 Max, Alibaba's brand-new flagship ($2/$6). DeepSeek V4 Flash serves the latest build, and popular models now fail over across multiple providers with prices pinned per model — an upstream's bad day never changes your bill.
Provider price cuts pass straight through, too: GPT 5.6 Luna dropped 80% to $0.20/$1.20 per million, and GPT 5.6 Terra to $2/$12 — OpenAI cut, you save, nothing to change on your side. And the machines themselves got a runtime upgrade: agents now ground their answers in what's actually on the machine and double-check their work before reporting done, and code search follows the git branch you're working on. New machines start on it today.
Everything above is live today. Connect a chat, mention the app in a PR, or just open the panel — your agents are one message away.